Sorry dear English Readers, I didn't spend time to translate by myself
The customer who shouts loudest: signal or noise?
A customer keeps pushing for one more feature: a signal worth following, or noise to filter out? Between product sprawl and lead user theory, four tools to decide without caving to the pressure of the moment.
Key takeaways
- A customer who won't let go might be signaling functional debt in the making (Mironov's "product sprawl"), or a genuine head start on the market (von Hippel's "lead user") — and in the moment, there's no way to tell which.
- It's not the volume of the signal that matters, but its representativeness: does the problem they describe actually affect other users, or only them?
- Four concrete tools — the recurrence test, the frequency × severity matrix, qualitative criteria, and RICE — to decide on new requests without relying on gut feeling or the pressure of the moment.
Sometimes, listening to your most insistent customer is a stroke of genius. Sometimes, it's the beginning of functional debt. And in the moment, it's almost impossible to know which one you're in.
This reflection grows out of the previous article I wrote on small steps — because a policy of small steps that never identifies which topics deserve the next step wouldn't make much sense. It takes me straight back to a coaching engagement I'm currently running with a team working on rebuilding an existing product, several months in, and eager to kick off a full product approach and improve the product's functional scope.
We're entering a phase where this team can deliver a major functional block — but on a single pilot site, with a single user giving us feedback... This pilot phase covers just one site out of twenty, and one user out of several dozen.
Moving into an improvement phase on this sub-scope right now carries a real risk: answering only one user's needs, or spending time on discovery for problems nobody else shares — all while there's still a good chunk of functional scope left to cover before we can truly retire the legacy system.
In the end, this is really a question of prioritizing the needs that are about to show up — and it struck me as fertile ground to revisit and list out prioritization tools, add some theory and argument around them, and some contradiction too, to properly stress-test the approach.
I'm sharing this article very much in the spirit of research, not settled truth, since this engagement is still ongoing. I'm using it as an opportunity to do my own research too, to validate or confirm what I already know.
The price of the customer who shouts loudest
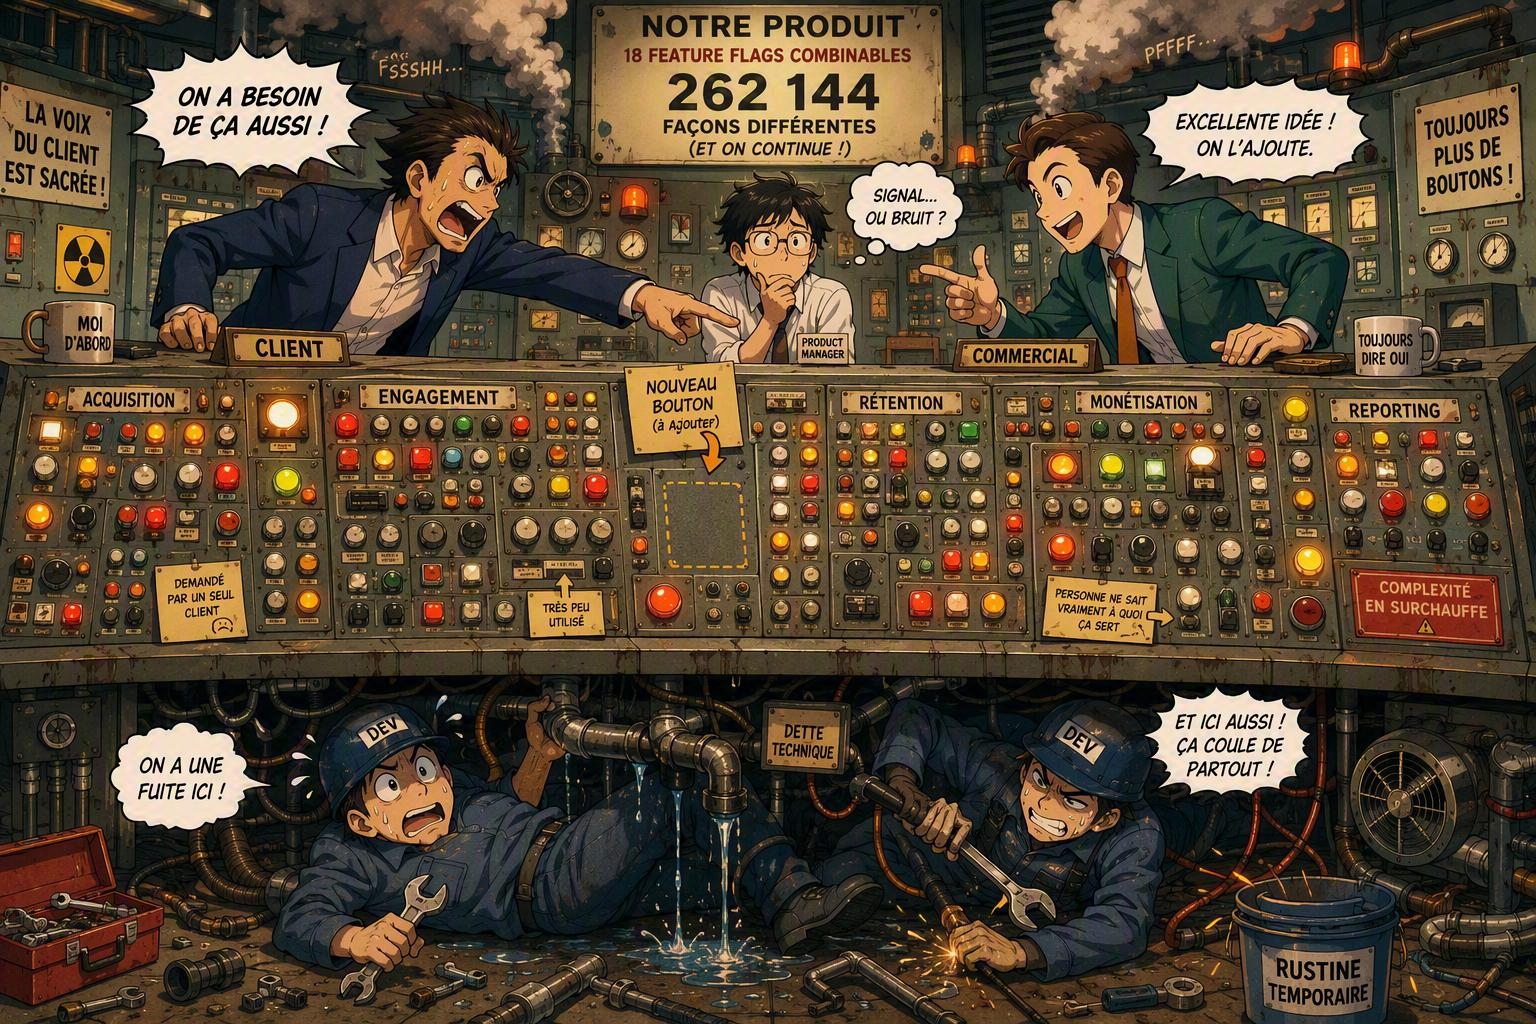
This situation is actually fairly well documented across product management literature. Whether it's bending to one customer's vision because they're our only customer right now, caving to whoever shouts loudest, or to the highest-paid person in the room: it all generates a pile of feature additions and even more possible product configurations — a phenomenon Rich Mironov actually gave a name to: "product sprawl." Here's how he describes the problem: *"fulfilling individual big-customer requests as sequenced by those big customers rarely converges on a reusable product"*¹.
In the end, we focus on one user's needs without necessarily paying attention to the maintenance cost of that addition, or more importantly, the overall value it brings to the product. Is this something that could interest other users too? If the proposed solution addresses a problem that exists elsewhere, will it actually serve our users broadly — or only the lead user?
This actually reminds me of another situation I ran into years ago, coaching a startup, where closing a sale was always conditional on adding some feature. Prospective clients seemed genuinely interested in the value we brought, but there was always a "but": "we'll buy it, but we need this…". And since these asks didn't always overlap with each other, they piled up in the backlog, slowing down our delivery with new priority tasks — and the sales never happened.
The risk in all this, ultimately, is failing to address the Jobs to Be Done (JTBD) — what genuinely needs solving. That's how Christensen defines JTBD² a topic is worth addressing once we've dug into the underlying problem and actually identified a real user need. But that requires running a Discovery process across a lot of topics, which inevitably piles up work upstream of delivery. So the real challenge here isn't about not bloating the product and its backlog — it's about focusing on features that are useful and actually used by users and customers.
Rich Mironov actually gives a sense of where this can lead at scale when the pattern repeats without any arbitration: in his own product, 18 feature flags can be combined in 262,144 different ways, and twelve separate on-premise releases are maintained in parallel for twenty customers who aren't ready to migrate¹.
If we stopped here, the conclusion would be simple: ignore the isolated noise. But that would mean forgetting a well-documented case where the exact opposite is true.
What if he was right before everyone else?
"Then again" — couldn't we have lead users to rely on, whose input would let us get ahead of the market?
Eric von Hippel defines this type of user as "lead users," who meet two criteria: they already face a need the rest of the market won't encounter until later, and they stand to gain a real benefit from a solution to it⁴. The average user, by contrast, can't yet imagine needs they haven't run into.
Von Hippel verified this mechanism across several industrial sectors far removed from software³ in scientific instruments and semiconductor process equipment, most commercially successful innovations were developed by users themselves, not by manufacturers (much like IBM, which designed the first component-insertion machine in-house before licensing the design to a manufacturer that later became a major player in the field). That said, it's not a universal law — in technical plastics or connector-fastening equipment, studied in the same paper, innovation remained dominated by manufacturers.
These examples cut against a practice I love, Lean Startup, where the goal is to validate problems, users, and solutions by working through strong hypotheses at every stage. Here, the idea is instead to focus on the needs of a lead user you trust. And as we've just seen, there are cases where that works. But at what cost? For what return on investment?
What von Hippel's mechanism explains isn't that a customer is sometimes right by chance, but why certain isolated signals are more reliable than the market average: a head start, not a personal whim.
Going back to our startup comparison, we probably did run into this kind of user. The real difficulty here is identifying them — especially when every user is raising different topics. Shouldn't a lead user, precisely, be deeply invested in the product (time, money, all kinds of resources...) and central to it — rather than being just one isolated user, or one isolated user's request?
To sum up: Mironov and von Hippel don't contradict each other. They're describing two different profiles of the customer who shouts loudest. The problem is our inability, in the moment, to tell them apart.
The test isn't the volume
With this theoretical framework laid out, let's come back to our original question, in the context of my ongoing coaching engagement. The baseline scope was defined through genuine multi-persona discovery, and validated in UAT by a pilot user — the only user with access to this functional scope at this stage. So the open question isn't about the baseline's features, which have already been tested, but about the new requests that will emerge once this new function is actually used in production. Which techniques can we apply to these choices?
The recurrence test
First instinct: Teresa Torres's recurrence test⁵. The principle: only treat a signal as a real topic once it comes back independently from several users — not the moment it shows up in a single isolated report. On the baseline scope itself, this has already been applied correctly — that's exactly what the upfront multi-persona discovery was: not building on a single piece of feedback, but looking for a signal that recurs across several independent users before investing.
The limit shows up with the new requests — the ones that will come in once that single user is actually using the feature daily, in production. With only one site live at this stage, there's no way to test their recurrence before other sites come online. So what Torres brings here isn't "I've found a recurring signal" — it's the reverse discipline: recognizing that we don't have the signal yet, and that the right call is to wait for more sites to go live before investing beyond the already-validated baseline, rather than extrapolating from a single person. A tool can also be there to say "we don't know yet," not only to decide.
The frequency × severity matrix
Second tool: a frequency × severity matrix⁶, to sort new requests as they come in rather than waiting until there are enough sites to rule on everything. The principle is simple: whatever breaks the already-validated baseline — a bug, a regression — is blocking and gets fixed regardless of how many reports come in. Whatever goes beyond that baseline — a new comfort request or feature — becomes a candidate to log, probably low priority as long as its frequency across other sites remains unknown. This keeps every piece of feedback from being treated the same way, when they don't call for the same urgency.
Qualitative criteria
Third tool, borrowed directly from von Hippel: for each new request, ask whether it reflects a structural trend that will likely affect other sites too — a regulatory constraint, a shared business practice, a common technical feature — or whether it's specific to this particular user's working habits. If it's structural, it deserves serious treatment even from a single report. If it's personal, it goes to low priority, with a clear conscience.
RICE
Fourth tool: the RICE framework⁷ — Reach, Impact, Confidence, Effort. Even at this early stage, we can score new requests: Reach, by estimating through similarity how many of the twenty sites would be affected; Impact; Confidence, deliberately low with a sample of one person — and that's information in itself, not a flaw in the tool; Effort. It gives a defensible way to say "not now" without dismissing the user's feedback out of hand.
Looking back at my own startup experience
In the end, we had to ask ourselves these same questions back in my startup days too, but I didn't have the keys — or most of these tools — to answer them. I was just starting out with the Club Agile Rhône Alpes, and I hadn't gone looking for enough of this material yet. Looking back, these practices would have helped enormously:
- the frequency × severity matrix would have let us list the topics coming in and compare them against each other — the different users' requests. If a request was genuinely only ever made once, that was already a fairly simple framework for prioritization;
- the same goes for RICE, adding in the notion of effort, even a rough one, which would have let us prioritize topics against each other;
- as for the recurrence test, we could have used it to validate, maybe even ahead of time, that the core feature was already useful to users — as a kind of pre-sale test phase.
These tools give us a framework to get away from stalling on the basis of some unverified statistic — the kind of "45% of features are never used"⁸ — just to push back a request. It doesn't hand us an automatic answer; it just gives us a way to decide without letting the loudest voice dictate the roadmap. And it gives us our decision-making framework going forward.
The test isn't the volume, it's representativeness
To wrap up the comparison with my current experience: these are tools we'd already planned to use in the engagement I've been describing, and this article gives me a chance to bring them back to the center with the theoretical argument behind them.
In the end, the test isn't the volume — how hard the customer pushes — but representativeness: does the problem they're describing actually affect others, or just them? And with the discipline we've laid out above — validating a minimum baseline, not reacting in the heat of the moment to a single signal, using simple tools to decide on new requests rather than gut feeling or the pressure of the moment — we now have several tools to decide, going forward, whether we're looking at a lead user or just a personal request that shouldn't be acted on.
Notes
¹ Rich Mironov, "Product Sprawl", mironov.com, November 28, 2021.
² Clayton Christensen, Taddy Hall, Karen Dillon, David S. Duncan, Competing Against Luck: The Story of Innovation and Customer Choice, HarperBusiness, 2016. See also Christensen Institute, "Jobs to Be Done Theory".
³ Eric von Hippel, "Lead Users: A Source of Novel Product Concepts", Management Science, vol. 32, no. 7, 1986, pp. 791-805 (full text).
⁴ Exact quotes: "Lead users face needs that will be general in a market place — but face them months or years before the bulk of that marketplace encounters them" and "Lead users are positioned to benefit significantly by obtaining a solution to those needs" — Eric von Hippel, "Lead Users: A Source of Novel Product Concepts," Management Science, 1986.
⁵ Teresa Torres, Continuous Discovery Habits: Discover Products that Create Customer Value and Business Value, Product Talk LLC, 2021.
⁶ "Frequency x Severity: Scoring Roadmap Requests", userintuition.ai.
⁷ Sean McBride, "RICE: Simple prioritization for product managers", Intercom, January 5, 2018.
⁸ A widely repeated but unreliable figure: it comes from a presentation by Jim Johnson (Standish Group) at the XP2002 conference ("ROI, It's Your Job"), based on just four internal-use applications, with no documented methodology. See the analysis by Mike Cohn and by fairness.coop (in French). Cited here precisely as an example of a figure not to take at face value.